The course’s skills. The same ones appear on your Certificate of Completion, so you can show what you covered.
Foundations of Reinforcement Learning
Exploration and Tabular Solution Methods
Value-Based Deep Reinforcement Learning
Policy Gradient Methods
Proximal Policy Optimization
From RL to RLHF: Aligning Language Models
Beyond PPO: DPO, RLAIF, GRPO and Verifiable Rewards
Reward Hacking, Alignment and Safety
About the course
A premium, advanced and hands-on course on reinforcement learning and RLHF, fully updated for 2026 and expanded to university depth. You will start from the mathematical foundations — Markov decision processes, rewards, policies, value functions, the Bellman equations and dynamic programming — and work through the exploration-exploitation trade-off, Monte Carlo and temporal-difference learning, Q-learning, function approximation and the deadly triad, Deep Q-Networks and their modern refinements (Double DQN, dueling architectures, prioritized replay). From there you will master modern policy optimization: REINFORCE, actor-critic (A2C/A3C), continuous control with DDPG, TD3 and Soft Actor-Critic, and Proximal Policy Optimization (PPO) in full detail, with real code on Gymnasium and Stable-Baselines3. The second half of the course turns to the techniques that made modern assistants possible: preference data collection and its legal obligations, reward models trained on human preferences, PPO-based RLHF as used to align systems such as ChatGPT and Claude, and the newer methods — Direct Preference Optimization (DPO), GRPO, RLAIF, Constitutional AI, and reinforcement learning with verifiable rewards (RLVR), the engine behind 2026 reasoning models. You will learn to spot and prevent reward hacking, reason about alignment and safety, evaluate aligned models honestly, and build real reward-model and DPO pipelines with Hugging Face TRL. Every concept is paired with correct, runnable Python and PyTorch code, worked numeric examples and exercises, and the course keeps a firm focus on the legal, licensing and ethical obligations around preference data and alignment. Includes a comprehensive final assessment.
Who it is for
For developers, engineers and technical professionals who build or integrate AI solutions. It belongs to Deep Learning & AI Models, on the IT Pro track.
What you need
Advanced level: assumes hands-on experience with AI in the course’s field.
Actor-Critic Methods: A2C and A3C50 min11 questions
Continuous Control: DDPG, TD3 and Soft Actor-Critic52 min11 questions
5
Module 5: Proximal Policy Optimization
2 lessons · 1 h 40 min · 22 questions
PPO in Detail52 min11 questions
Implementing PPO with Stable-Baselines348 min11 questions
6
Module 6: From RL to RLHF: Aligning Language Models
4 lessons · 3 h 22 min · 44 questions
Why Language Models Need Alignment: Pretraining, SFT and the RLHF Pipeline48 min11 questions
Preference Data: Collection, Annotation Quality and Legal Obligations50 min11 questions
Reward Models from Human Preferences52 min11 questions
PPO for RLHF: How ChatGPT and Claude Were Aligned52 min11 questions
7
Module 7: Beyond PPO: DPO, RLAIF, GRPO and Verifiable Rewards
4 lessons · 3 h 24 min · 44 questions
Direct Preference Optimization (DPO)52 min11 questions
RLAIF and Constitutional AI50 min11 questions
GRPO and Modern Alignment in 202650 min11 questions
RLVR: Verifiable Rewards and the Training of Reasoning Models52 min11 questions
8
Module 8: Reward Hacking, Alignment and Safety
2 lessons · 1 h 40 min · 22 questions
Reward Hacking and Specification Gaming50 min11 questions
Alignment, Safety and Responsible RLHF50 min11 questions
9
Module 9: RLHF in Practice and Evaluation
4 lessons · 3 h 12 min · 44 questions
Training a Reward Model with TRL48 min11 questions
DPO Fine-Tuning with TRL48 min11 questions
Evaluating Aligned Models50 min11 questions
Real-World Applications and Course Wrap-Up46 min11 questions
10
Module 10: Final Quiz — Reinforcement Learning and RLHF
1 lesson · 55 min · 30 questions
Final Assessment — Reinforcement Learning and RLHF55 min30 questions
By email
Email me the course syllabus
Modules and lessons in order, plus the link to the preview of lesson 1 — so you can decide at your own pace.
Check your inbox
We sent a confirmation email to . One click there and we send you the course syllabus.
Not there? Check Spam or Promotions and move it to Inbox.
How you learn
You read the lesson, ask the AI Professor right on the page and check what you remember.
Lesson 1 · 46 min
What Reinforcement Learning Is and Why It Matters in 2026
Reinforcement learning (RL) is the branch of machine learning concerned with learning to act. Instead of learning from a fixed dataset of labelled examples, an RL agent learns by interacting with an environment: it takes actions, observes the consequences, and gradually improves its behaviour to maximise a numerical reward.
The first lines of lesson 1 of this course.
Read the free preview, no account needed.
You read the lesson at your own pace
Written lessons, with examples and exercises. Your progress is saved automatically, so you can pick up where you left off.
You ask the AI Professor inside the lesson
Select a passage and it explains it, gives you an example or tells you why it matters. You can type or talk to it, in English.
You check what you remember
Every lesson has its own quiz, with explanations for the answers: 350 questions across the course. The professor also summarizes the lesson and prepares review flashcards.
You get the Certificate of Completion
Once you complete the lessons and reach the minimum quiz score, you issue it from your account, with a unique number, publicly verifiable.
The AI Professor is included in your subscription, per-course access included, with a monthly fair-use limit. It is an AI system, not a human teacher, and its answers may contain errors; details in the Terms. See how the AI Professor works.
You leave with proof anyone can check
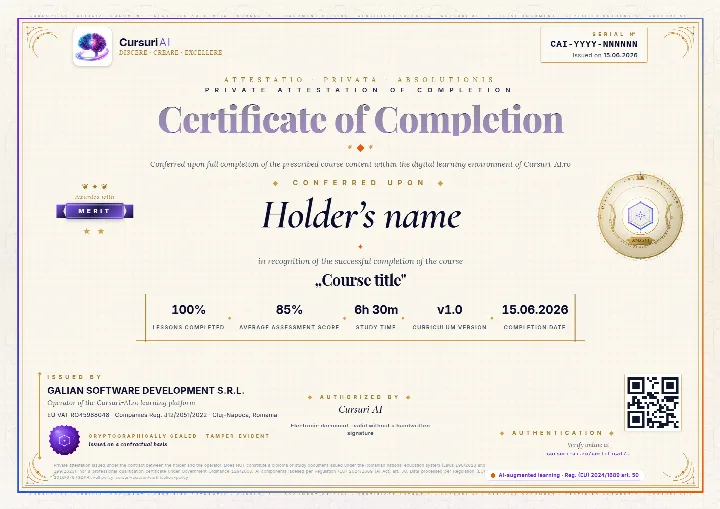
The Certificate of Completion for “Reinforcement Learning and RLHF: Training and Aligning AI Models”: a private attestation with a unique number and a QR code. A recruiter confirms it is authentic on the public verification page, with no account and no cost.
The real document, an A4 PDF, shown here with sample data. Yours carries your name, the course “Reinforcement Learning and RLHF: Training and Aligning AI Models”, the serial number, the issue date and the tier you earned; the QR code in the image is decorative.
Anyone can verify it
Public verification page, QR code and cryptographic fingerprint, with no account for the person checking.
You show it where it counts
Add it to your CV and LinkedIn profile; a recruiter confirms authenticity with one click.
It says exactly what it attests
The course, the tier you earned (Pass, Merit or Distinction), the serial number and the issue date, plus the percentage of lessons completed.
A private attestation of course completion. It is NOT a diploma or a state-recognised qualification under Romanian Laws 198/2023, 199/2023 or Government Ordinance 129/2000; employers may take it into account at their own discretion. Certification policy.
Pricing
Just this course or the whole IT Pro track
Billed monthly, in EUR. You can stop the renewal anytime from your account, and access starts right after payment. Prices are totals, with VAT included at the rate of your country.
Just this course
Reinforcement Learning and RLHF: Training and Aligning AI Models
€99per month, VAT includedNo commitment: stop the renewal anytime
Subscriptions renew automatically; you can stop the renewal anytime from your account, and access stays until the end of the period already paid for. As digital content with immediate access, see the withdrawal conditions.
About the course, the price, the AI Professor and the certificate.
What will I learn in “Reinforcement Learning and RLHF: Training and Aligning AI Models”?
A premium, advanced and hands-on course on reinforcement learning and RLHF, fully updated for 2026 and expanded to university depth. You will start from the mathematical foundations — Markov decision processes, rewards, policies, value functions, the Bellman equations and dynamic programming — and work through the exploration-exploitation trade-off, Monte Carlo and temporal-difference learning, Q-learning, function approximation and the deadly triad, Deep Q-Networks and their modern refinements (Double DQN, dueling architectures, prioritized replay). From there you will master modern policy optimization: REINFORCE, actor-critic (A2C/A3C), continuous control with DDPG, TD3 and Soft Actor-Critic, and Proximal Policy Optimization (PPO) in full detail, with real code on Gymnasium and Stable-Baselines3. The second half of the course turns to the techniques that made modern assistants possible: preference data collection and its legal obligations, reward models trained on human preferences, PPO-based RLHF as used to align systems such as ChatGPT and Claude, and the newer methods — Direct Preference Optimization (DPO), GRPO, RLAIF, Constitutional AI, and reinforcement learning with verifiable rewards (RLVR), the engine behind 2026 reasoning models. You will learn to spot and prevent reward hacking, reason about alignment and safety, evaluate aligned models honestly, and build real reward-model and DPO pipelines with Hugging Face TRL. Every concept is paired with correct, runnable Python and PyTorch code, worked numeric examples and exercises, and the course keeps a firm focus on the legal, licensing and ethical obligations around preference data and alignment. Includes a comprehensive final assessment.
The course has 10 modules and 30 lessons, with 350 quiz questions. The full curriculum, module by module, is shown on the course page.
Do I need prior experience for this course?
Yes. The course is Advanced level and assumes hands-on experience with AI in its field.
How long does the course take?
The estimated duration is about 25 hours, across 30 lessons. You learn at your own pace, and your progress is saved automatically at every lesson, so you can pick up where you left off.
How much does it cost, and which plan do I need?
Access to this course alone costs €99 per month. The course is also included in the IT Pro bundle, €399 per month for all 25 IT Pro courses, and in All Access, €499 per month for the whole international catalog.
Plans are billed monthly, in EUR. Every price is a total, with VAT included at the rate of your country. Compare the plans.
Can I read part of the course before paying?
Yes. You can read a free preview of lesson 1, “What Reinforcement Learning Is and Why It Matters in 2026”, without an account. The preview shows you how the lesson is written; the rest of the lesson and the other lessons open after payment.
How does the AI Professor help me in this course?
The AI Professor is built into every lesson and starts from the lesson you have open: it explains the passages you select, gives you examples, summarizes the lesson, tests you with a quiz and prepares review flashcards. You can type or talk to it, in English.
It is included in your subscription, per-course access included, with a monthly fair-use limit. It is an AI system, not a human teacher, and its answers may contain errors; details in the Terms.
Do I get a certificate when I finish the course?
When you meet the completion thresholds shown on the platform (lessons completed and the minimum quiz score), you can issue your Certificate of Completion for “Reinforcement Learning and RLHF: Training and Aligning AI Models” from your account, with a unique number, publicly verifiable on the site.
It is a private attestation of course completion, issued by GALIAN SOFTWARE DEVELOPMENT SRL. It is NOT a diploma or a state-recognised qualification under Romanian Laws 198/2023, 199/2023 or Government Ordinance 129/2000; employers may take it into account at their own discretion. Details in the Certification policy.
Does the subscription renew automatically? How do I stop it?
Yes. Course access and the bundles are subscriptions that renew automatically at the end of each monthly billing period. You can see the next renewal date in your account at any time.
You can stop the renewal at any time, from your account or by email, with no other formality. Access stays active until the end of the period already paid for, and no pro-rata refund is made for a period already started, except in the cases provided by law. Your progress stays saved in your account. Details in the Terms & Conditions, section 5.5.
Can my company buy this course for a team?
Yes. Company plans give a team access to the courses, with a dashboard where you follow each member’s progress and manage seats centrally. See the plans for companies.
From the same track
Similar courses
All of them are included in the IT Pro bundle, at about €16 per course, or you can take them separately, at €99 a month each.
Master fine-tuning of open-source LLMs: LoRA, QLoRA, datasets, DPO, quantization (GGUF/GPTQ/AWQ) and self-hosting with Ollama and vLLM. Advanced course, 2026.
“Reinforcement Learning and RLHF: Training and Aligning AI Models”: 30 lessons and about 25 hours of content, with your progress saved at every lesson.
Instant access after payment, on computer, tablet or phone.
AI Professor in every lesson, included in your subscription.
Certificate of Completion, publicly verifiable.
Just this course
€99/month
VAT included · stop the renewal anytime from your account
ChatGPT, OpenAI, Claude, Anthropic, Gemini, Google, Microsoft 365 Copilot, Cursor, Midjourney and the other product and company names mentioned are trademarks or trade names of their respective owners. Cursuri-AI.ro is an independent training provider and is not affiliated with, sponsored by or endorsed by any of them.